Python Web Scraping with BeautifulSoup
Learn web scraping with Python, requests and BeautifulSoup: download pages politely, parse HTML, follow pagination and save clean CSV data.
Web scraping means writing a program that opens a web page, reads the HTML like a person would read the screen, and copies the pieces of information you need into a file or a database. Price lists, job posts, sports tables, book catalogues, exam results and public notices are all typical targets. Doing this by hand takes hours. A short Python script does it in seconds and can repeat the job every day.
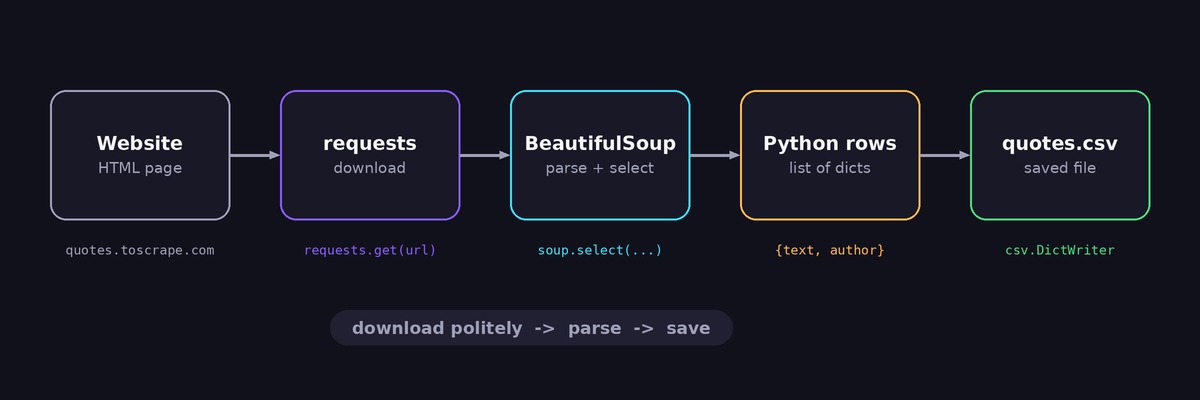
This tutorial takes you from zero to a complete working scraper. You will install the tools, download a page politely, find the right elements with the browser's inspector, extract text and links with BeautifulSoup, follow pagination, save everything to a CSV file and add the safety habits that keep your scraper from being blocked. We use a website called quotes.toscrape.com, which was built on purpose for practising scraping, so you can run every example without worrying about anyone's terms of service.
Before you start: is scraping allowed?
Scraping sits in a grey area, so build good habits from the first script. Check these things before you scrape any real website:
- Look for an official API or a download button. Many sites offer their data as JSON, CSV or RSS. An API is faster, more stable and clearly allowed.
- Read the terms of use. Some websites forbid automated access. If they do, do not scrape them.
- Open
/robots.txt. For examplehttps://example.com/robots.txt. It lists the paths that automated programs should avoid. - Do not collect personal data, and do not copy articles or images to republish them. Facts such as a price or a date are one thing, creative content is another.
- Be gentle. Your script can send hundreds of requests per minute, which can slow down a small website. Add delays and keep the number of requests low.
This is general guidance and not legal advice. When your project is commercial, ask the website owner for permission.
Set up your project
Create a folder for the project and a virtual environment, so that the packages you install do not mix with other projects:
mkdir quotes-scraper
cd quotes-scraper
python -m venv venv

# Windows
venv\Scripts\activate
# macOS and Linux
source venv/bin/activate

pip install requests beautifulsoup4
Two packages do the work. requests downloads a web page, and beautifulsoup4 (imported as bs4) reads the HTML and lets you search it. A third package, lxml, is an optional faster parser. The built-in html.parser is enough for learning.
Step 1: Download a page
Start with the simplest possible script:
import requests

url = "https://quotes.toscrape.com/"
headers = {"User-Agent": "Mozilla/5.0 (compatible; LearningScraper/1.0)"}

resp = requests.get(url, headers=headers, timeout=15)
print(resp.status_code)
print(resp.headers.get("Content-Type"))
print(resp.text[:300])
Run it. The first line should print 200, which means success. Status 403 means the server refused you, 404 means the page does not exist and 429 means you are sending too many requests. The timeout=15 argument is not optional in real projects: without it a stuck server can freeze your script forever. Our guide to timeouts, retries and sessions in requests explains the details.
The User-Agent header tells the server which program is asking. Many servers reject the default value python-requests, so send a clear and honest name instead of pretending to be a browser from another company.
Step 2: Look at the page like a scraper
Open https://quotes.toscrape.com/ in your browser, right-click one quote and choose Inspect. The developer tools show the HTML behind the page. You will see a structure like this (shortened):
<div class="quote">
  <span class="text">"The world as we have created it..."</span>
  <span>by <small class="author">Albert Einstein</small></span>
  <div class="tags">
    <a class="tag" href="/tag/change/page/1/">change</a>
    <a class="tag" href="/tag/deep-thoughts/page/1/">deep-thoughts</a>
  </div>
</div>
This is the most important skill in scraping: reading the structure. Every quote lives in a div with the class quote. Inside it, the text is in a span with class text, the author is in a small with class author, and each tag is a link with class tag. Your code will repeat this pattern for each quote. Always check View page source as well, because it shows what requests receives. If the data is missing there, the page builds it with JavaScript, and you need another approach, described in this guide to finding the hidden JSON API.
Step 3: Parse the HTML with BeautifulSoup
Give the HTML text to BeautifulSoup and it builds a tree that you can search:
from bs4 import BeautifulSoup

soup = BeautifulSoup(resp.text, "html.parser")

print(soup.title.get_text(strip=True))

first = soup.find("div", class_="quote")
print(first.find("span", class_="text").get_text(strip=True))
print(first.find("small", class_="author").get_text(strip=True))
The most useful methods are these:
find(tag, class_=..., id=...)returns the first match, orNone.find_all(tag, ...)returns a list of all matches.select_one("css selector")andselect("css selector")do the same with CSS selectors, such asdiv.quote span.text.element.get_text(strip=True)returns the text inside an element without extra whitespace.element.get("href")returns an attribute value, orNoneif it is missing.
Beginners often wonder when to use which style. Use CSS selectors when you copy the structure from the browser, because they are compact. Use find and find_all when you prefer plain Python arguments. Both give the same result. If you ever see the error 'NoneType' object has no attribute 'get_text', a search found nothing. Read our article on fixing that error for a full debugging routine.
Step 4: Extract all items on the page
Now loop over every quote and collect the fields into a list of dictionaries. A dictionary per row is easy to save and easy to read:
quotes = []

for card in soup.select("div.quote"):
    text = card.select_one("span.text").get_text(strip=True)
    author = card.select_one("small.author").get_text(strip=True)
    tags = [t.get_text(strip=True) for t in card.select("a.tag")]
    quotes.append({
        "text": text,
        "author": author,
        "tags": ", ".join(tags),
    })

print(len(quotes), "quotes found")
print(quotes[0])
The list comprehension on the tags line is a compact way to build a list from all matching links. ", ".join(tags) turns the list into one string so that it fits in a single CSV cell. On this site, you should see ten quotes for page one.
Step 5: Follow the pagination
One page is rarely enough. At the bottom of the site there is a "Next" button. In the HTML it is an li with class next that contains a link. Your scraper should follow that link until there is no more "Next". Two details matter. The link is relative, such as /page/2/, so you must combine it with the base address, and you must stop when the button is missing. Python's urljoin solves the first one:
import time
import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin

BASE = "https://quotes.toscrape.com/"
HEADERS = {"User-Agent": "Mozilla/5.0 (compatible; LearningScraper/1.0)"}

def scrape_all(max_pages=20):
    session = requests.Session()
    session.headers.update(HEADERS)
    url, rows, pages = BASE, [], 0

    while url and pages < max_pages:
        resp = session.get(url, timeout=15)
        resp.raise_for_status()
        soup = BeautifulSoup(resp.text, "html.parser")

        for card in soup.select("div.quote"):
            rows.append({
                "text": card.select_one("span.text").get_text(strip=True),
                "author": card.select_one("small.author").get_text(strip=True),
                "tags": ", ".join(t.get_text(strip=True) for t in card.select("a.tag")),
            })

        nxt = soup.select_one("li.next a")
        url = urljoin(url, nxt["href"]) if nxt else None
        pages += 1
        time.sleep(1)          # be polite: one request per second

    return rows
Notice the three safety features. max_pages stops an endless loop if the site misbehaves. raise_for_status() turns a 404 or 500 into an exception immediately. time.sleep(1) slows the scraper to a friendly pace. The Session reuses the connection, which makes the loop faster than calling requests.get every time.
Step 6: Save the data to CSV
CSV is the easiest format to open in Excel or Google Sheets. Use the csv module and the encoding utf-8-sig, so that special characters such as curly quotes look right in Excel:
import csv

rows = scrape_all()

with open("quotes.csv", "w", newline="", encoding="utf-8-sig") as f:
    writer = csv.DictWriter(f, fieldnames=["text", "author", "tags"])
    writer.writeheader()
    writer.writerows(rows)

print("Saved", len(rows), "rows to quotes.csv")
If your file shows strange symbols in Excel, the cause and fix are explained in our article about Python CSV encoding. If you prefer pandas, pandas.DataFrame(rows).to_csv("quotes.csv", index=False, encoding="utf-8-sig") does the same in one line.
Step 7: Check robots.txt in code
Python can read robots.txt for you. Add a check before you request a path:
from urllib.robotparser import RobotFileParser

rp = RobotFileParser()
rp.set_url("https://quotes.toscrape.com/robots.txt")
rp.read()

allowed = rp.can_fetch("LearningScraper", "https://quotes.toscrape.com/page/2/")
print("Allowed:", allowed)
If can_fetch returns False for a path, skip it. Some sites also set a Crawl-delay, which you can read with rp.crawl_delay("LearningScraper") and use as your sleep time.
Habits that keep a scraper alive
A scraper that works today may break tomorrow, so write it as if someone else has to maintain it. These habits matter most:
- Cache what you download. While you build the parser, save the HTML to a file and parse the file. You avoid repeated requests and your experiments run instantly.
- Keep selectors in one place. Put them in constants at the top of the file, so that a layout change means editing one line.
- Check your results. If you expect about ten items per page and get zero, stop and report instead of saving an empty file.
- Handle missing fields. Not every item has every field. Use a small helper that returns an empty string when an element is absent.
- Log what you do. Print the URL and the number of items for every page, so you can see where a run stopped.
- Respect rate limits. If you receive status 429, wait longer. The
Retry-Afterheader often tells you how long.
Common problems and where to look
- You get an empty list. Save the HTML and check that the data is in it. If it is not, the content comes from JavaScript.
- You get status 403. The server dislikes your request. Check the User-Agent and your request rate, and make sure the site allows automated access.
- Text looks like gibberish. The encoding is wrong. Set
resp.encoding = resp.apparent_encodingbefore readingresp.text. - The script freezes. You have no timeout. Add
timeout=15to every request. - The script crashes on one page. An optional element is missing. Use defensive helpers, as explained in the NoneType article above.
Where to go next
Once the basic scraper works, you can grow it step by step. Schedule it to run every morning with cron on a server or a free Render service, and have it send you a summary through a Telegram bot. You can also combine scraping with the file tricks from our article about automating daily tasks with Python.
Frequently asked questions
Is BeautifulSoup or Scrapy better?
BeautifulSoup is a parser: it reads HTML and you write the rest. Scrapy is a complete framework with queues, retries, pipelines and concurrency. For small and medium jobs, requests plus BeautifulSoup is simpler and easier to understand. Move to Scrapy when you crawl thousands of pages regularly.
Can BeautifulSoup scrape pages that use JavaScript?
Not by itself, because it only reads the HTML that you give it. Often the page loads its data from a JSON address that you can call directly. If that does not work, a browser automation tool such as Playwright can render the page first.
Which parser should I use?
html.parser needs no installation and works for most pages. lxml is faster and a bit more forgiving with broken HTML. html5lib is the slowest and the closest to how browsers parse. Test with another parser when a selector works in the browser but not in your script.
How do I avoid getting blocked?
Be an easy visitor: identify your script, slow down, cache pages, avoid scraping at peak hours and follow robots.txt. If a website blocks you despite that, it does not want automated access, so respect it or ask for permission.
Is it legal to scrape a website?
It depends on the country, the website's terms and the kind of data. Public facts are treated differently from copyrighted content and personal data. Read the terms, prefer official APIs and take legal advice for commercial projects.
Final thoughts
Scraping with BeautifulSoup follows the same four steps every time: download the page politely, study its structure in the browser, pick out the elements with selectors and save the result. The rest is care: timeouts, delays, checks and respect for the website. Practise on quotes.toscrape.com until the flow feels natural, and then apply it to your own projects, always with the owner's rules in mind.